October 16, 2026
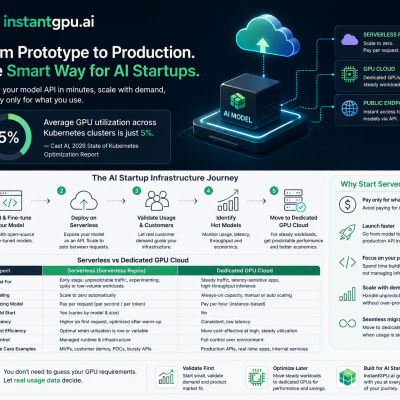
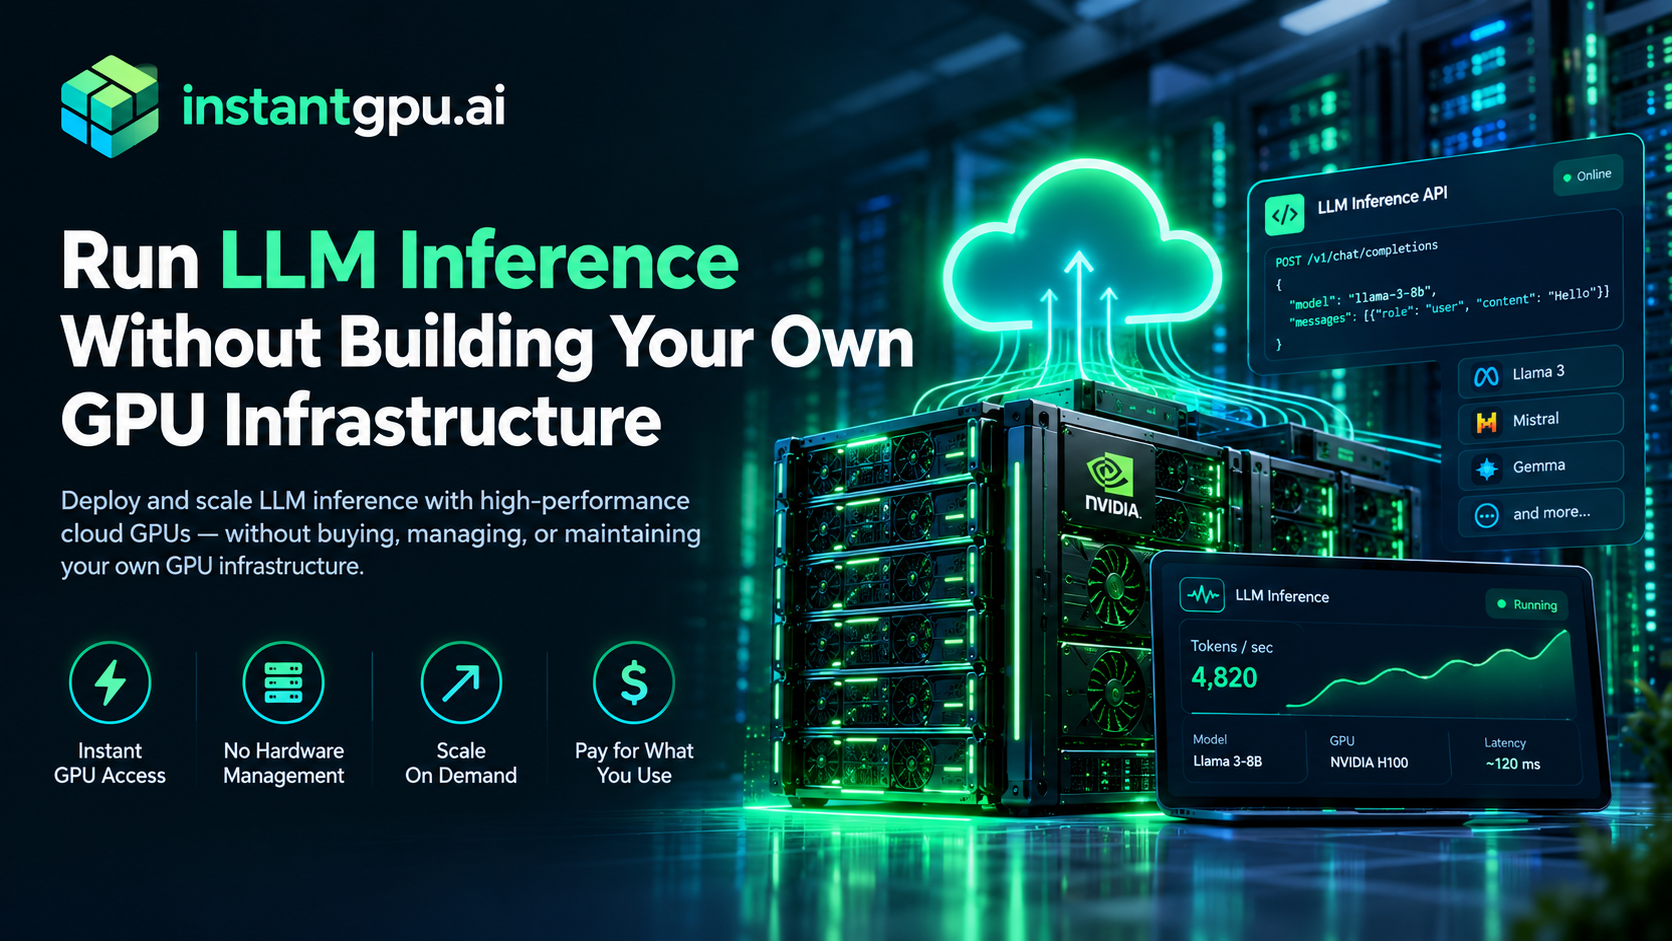
LLM Inference Hosting Run LLM Inference Without Building Your Own GPU Infrastructure Running a large language model in production is very different from experimenting with a model on...
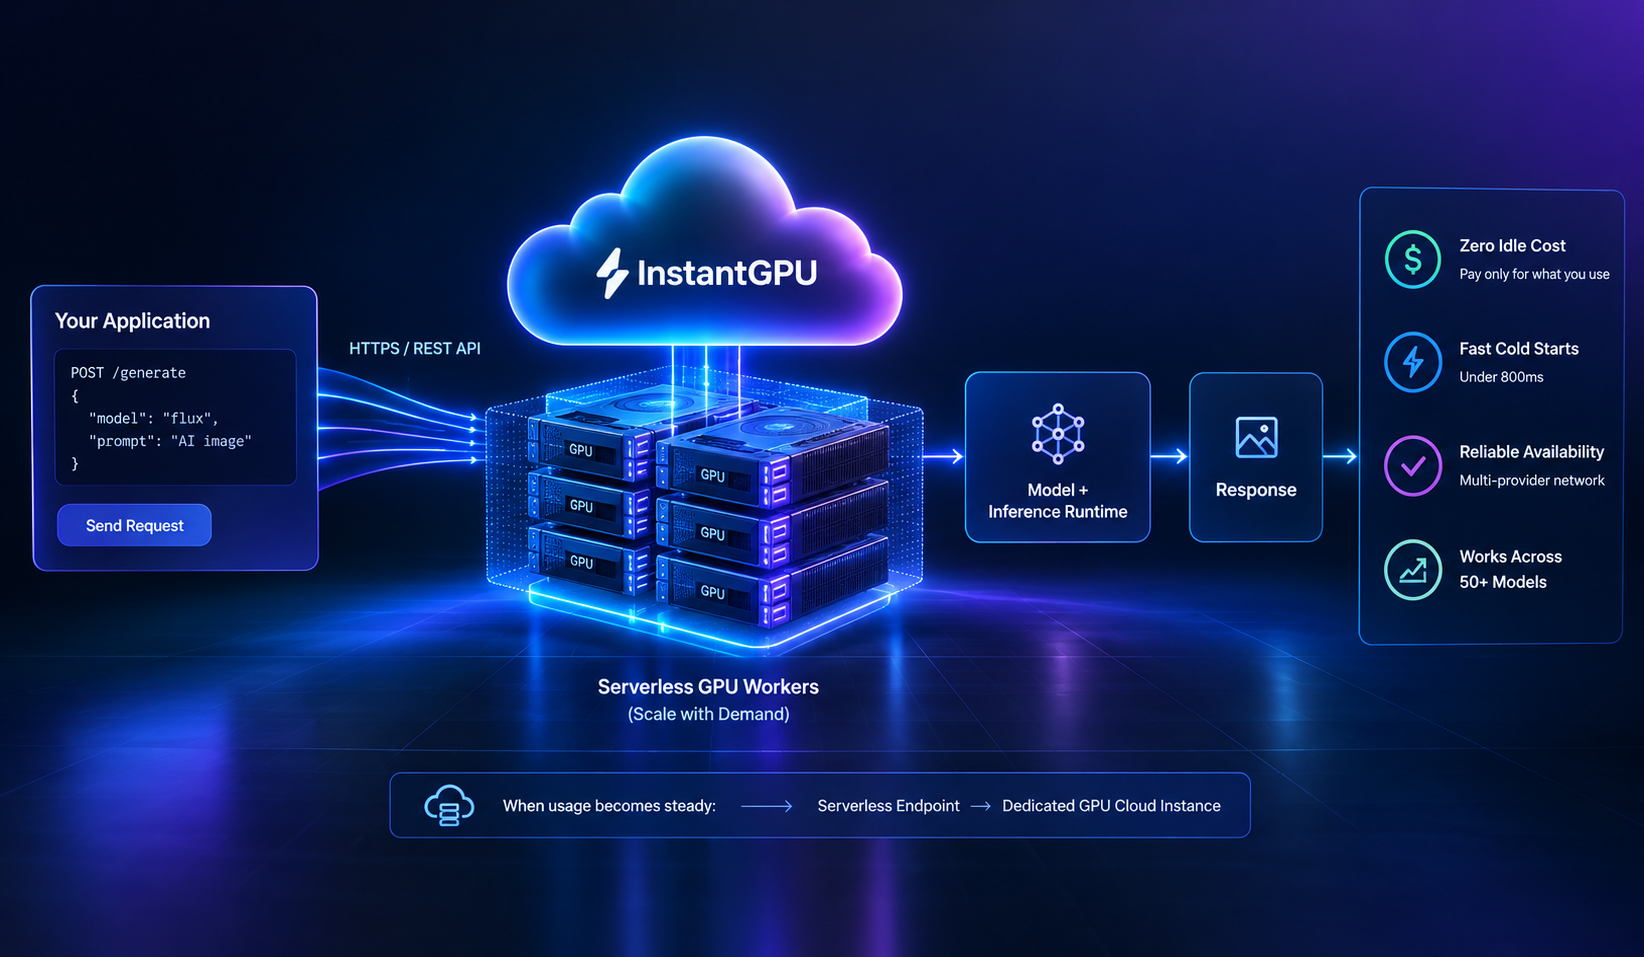
What a Truly Serverless GPU Platform Actually Looks Like In short: a lot of platforms call themselves “serverless” while still charging for idle time, or scaling up fast...