Get a GPU cloud with SSH access push your AI code to a repo, or launch directly. We handle containers, scaling, cold starts, and infrastructure — you ship features.
4 GPU families
per hour billing
SSH / VM-level access
Live pricing across 100+ GPU types on one GPU cloud platform, from cost-efficient entry-level GPUs to the latest frontier hardware.
| GPU | VRAM | Max GPUs | Best For | $ / HR From | Availability | |
|---|---|---|---|---|---|---|
| NVIDIA H100 SXM | 80GB | Up to 1x | Large model training & high-throughput inference | $2.41 / hr | Available Now | Launch |
| NVIDIA H100 NVL | 94GB | Up to 1x | Large model training & high-throughput inference | $2.78 / hr | Limited | Launch |
| NVIDIA H100 PCIe | 80GB | Up to 8x | Large model training & high-throughput inference | $2.89 / hr | Limited | Launch |
| NVIDIA H100 PCIE | 80GB | Up to 1x | Large model training & high-throughput inference | $3.34 / hr | Available Now | Launch |
| NVIDIA H200 NVL | 140GB | Up to 1x | Frontier LLM training & long-context inference | $3.47 / hr | Available Now | Launch |
| NVIDIA H200 | 140GB | Up to 1x | Frontier LLM training & long-context inference | $3.98 / hr | Available Now | Launch |
| NVIDIA H200 SXM | 141GB | Up to 8x | Frontier LLM training & long-context inference | $4.59 / hr | Available Now | Launch |
| NVIDIA B200 | 180GB | Up to 8x | Frontier LLM training & long-context inference | $6.79 / hr | Limited | Launch |
| NVIDIA B300 | 288GB | Up to 8x | Frontier LLM training & long-context inference | $7.89 / hr | Limited | Launch |
| NVIDIA A100 PCIE | 40GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.736 / hr | Available Now | Launch |
| NVIDIA A800 PCIE | 80GB | Up to 1x | Large model training & high-throughput inference | $0.882 / hr | Available Now | Launch |
| NVIDIA A100 SXM4 | 80GB | Up to 1x | Large model training & high-throughput inference | $1.06 / hr | Available Now | Launch |
| NVIDIA A100 PCIe | 80GB | Up to 8x | Large model training & high-throughput inference | $1.59 / hr | Limited | Launch |
| NVIDIA A100 SXM | 80GB | Up to 8x | Large model training & high-throughput inference | $1.59 / hr | Available Now | Launch |
| NVIDIA a10080g | 80GB | Up to 1x | Large model training & high-throughput inference | $1.65 / hr | Available Now | Launch |
| NVIDIA L4 | 22GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.336 / hr | Limited | Launch |
| NVIDIA L40S | 45GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.801 / hr | Available Now | Launch |
| NVIDIA L40 | 48GB | Up to 10x | Fine-tuning, mid-size training, inference | $0.820 / hr | Available Now | Launch |
| NVIDIA l4 | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.950 / hr | Available Now | Launch |
| NVIDIA RTX 5080 | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.166 / hr | Available Now | Launch |
| NVIDIA RTX 5090 | 32GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.401 / hr | Limited | Launch |
| NVIDIA RTX 4070S | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.084 / hr | Available Now | Launch |
| NVIDIA RTX 4070 | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.096 / hr | Available Now | Launch |
| NVIDIA RTX 4070 Ti | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.109 / hr | Available Now | Launch |
| NVIDIA RTX 4070S Ti | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.136 / hr | Available Now | Launch |
| NVIDIA RTX 4080 | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.269 / hr | Available Now | Launch |
| NVIDIA RTX 4080S | 32GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.313 / hr | Available Now | Launch |
| NVIDIA RTX 4090 | 48GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.373 / hr | Available Now | Launch |
| NVIDIA RTX 4080 SUPER | 16GB | Up to 4x | Cost-efficient inference & prototyping | $0.500 / hr | Available Now | Launch |
| NVIDIA RTX A4000 | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.109 / hr | Available Now | Launch |
| NVIDIA RTX A6000 | 45GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.404 / hr | Limited | Launch |
| NVIDIA A40 | 48GB | Up to 10x | Fine-tuning, mid-size training, inference | $0.490 / hr | Available Now | Launch |
| NVIDIA RTX PRO 6000 MaxQ | 96GB | Up to 2x | Large model training & high-throughput inference | $0.500 / hr | Available Now | Launch |
| NVIDIA a6000 | 48GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.500 / hr | Available Now | Launch |
| NVIDIA RTX 6000Ada | 48GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.535 / hr | Available Now | Launch |
| NVIDIA PRO 6000 MIG 24GB | 24GB | Up to 32x | Image/video generation, mid-tier AI workloads | $0.590 / hr | Available Now | Launch |
| NVIDIA RTX 6000 Ada | 48GB | Up to 8x | Fine-tuning, mid-size training, inference | $0.840 / hr | Limited | Launch |
| NVIDIA PRO 6000 MIG 48GB | 48GB | Up to 16x | Fine-tuning, mid-size training, inference | $1.09 / hr | Available Now | Launch |
| NVIDIA RTX PRO 6000 WS | 96GB | Up to 1x | Large model training & high-throughput inference | $1.27 / hr | Available Now | Launch |
| NVIDIA RTX PRO 6000 S | 96GB | Up to 1x | Large model training & high-throughput inference | $1.40 / hr | Available Now | Launch |
| NVIDIA RTX PRO 6000 Max-Q | 96GB | Up to 1x | Large model training & high-throughput inference | $1.55 / hr | Available Now | Launch |
| NVIDIA RTX PRO 6000 | 96GB | Up to 9x | Large model training & high-throughput inference | $2.09 / hr | Available Now | Launch |
| NVIDIA RTX PRO 6000 WK | 96GB | Up to 8x | Large model training & high-throughput inference | $2.19 / hr | Limited | Launch |
| NVIDIA MI300X | 192GB | Up to 8x | Frontier LLM training & long-context inference | $2.39 / hr | Available Now | Launch |
| NVIDIA RTX 4000Ada | 20GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.188 / hr | Available Now | Launch |
| NVIDIA RTX A5000 | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.233 / hr | Available Now | Launch |
| NVIDIA RTX 2000 Ada | 16GB | Up to 8x | Cost-efficient inference & prototyping | $0.240 / hr | Available Now | Launch |
| NVIDIA RTX A4500 | 20GB | Up to 4x | Image/video generation, mid-tier AI workloads | $0.250 / hr | Available Now | Launch |
| NVIDIA RTX 4500Ada | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.259 / hr | Available Now | Launch |
| NVIDIA RTX 4000 Ada | 20GB | Up to 8x | Image/video generation, mid-tier AI workloads | $0.280 / hr | Limited | Launch |
| NVIDIA RTX 5880Ada | 48GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.737 / hr | Available Now | Launch |
| NVIDIA RTX 5000 Ada | 32GB | Up to 4x | Image/video generation, mid-tier AI workloads | $0.830 / hr | Available Now | Launch |
| NVIDIA GTX TITAN X | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.049 / hr | Available Now | Launch |
| NVIDIA GTX 1070 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.049 / hr | Available Now | Launch |
| NVIDIA GTX 1660 | 6GB | Up to 1x | Entry-level inference & experimentation | $0.049 / hr | Available Now | Launch |
| NVIDIA RTX 3060 | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.050 / hr | Available Now | Launch |
| NVIDIA GTX 1080 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.052 / hr | Available Now | Launch |
| NVIDIA GTX 1070 Ti | 8GB | Up to 1x | Entry-level inference & experimentation | $0.053 / hr | Available Now | Launch |
| NVIDIA RTX 3060 Ti | 8GB | Up to 1x | Entry-level inference & experimentation | $0.056 / hr | Available Now | Launch |
| Titan Xp | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.056 / hr | Available Now | Launch |
| NVIDIA GTX 1080 Ti | 11GB | Up to 1x | Entry-level inference & experimentation | $0.056 / hr | Available Now | Launch |
| NVIDIA RTX 2070 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.056 / hr | Available Now | Launch |
| NVIDIA Quadro P4000 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.058 / hr | Available Now | Launch |
| NVIDIA GTX 1660 S | 6GB | Up to 1x | Entry-level inference & experimentation | $0.058 / hr | Available Now | Launch |
| NVIDIA RTX 2060 | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.060 / hr | Available Now | Launch |
| NVIDIA RTX 2060S | 8GB | Up to 1x | Entry-level inference & experimentation | $0.066 / hr | Available Now | Launch |
| NVIDIA GTX 1660 Ti | 6GB | Up to 1x | Entry-level inference & experimentation | $0.068 / hr | Available Now | Launch |
| NVIDIA RTX 2070S | 8GB | Up to 1x | Entry-level inference & experimentation | $0.068 / hr | Available Now | Launch |
| NVIDIA RTX 3060 laptop | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.068 / hr | Available Now | Launch |
| NVIDIA RTX 3080 | 10GB | Up to 1x | Entry-level inference & experimentation | $0.069 / hr | Available Now | Launch |
| NVIDIA RTX 3070 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.069 / hr | Available Now | Launch |
| NVIDIA RTX 5060 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.070 / hr | Available Now | Launch |
| NVIDIA RTX 2080 Ti | 11GB | Up to 1x | Entry-level inference & experimentation | $0.082 / hr | Available Now | Launch |
| NVIDIA RTX 4060 Ti | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.085 / hr | Available Now | Launch |
| NVIDIA RTX 4060 | 8GB | Up to 1x | Entry-level inference & experimentation | $0.088 / hr | Available Now | Launch |
| Titan V | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.090 / hr | Available Now | Launch |
| NVIDIA RTX 3070 Ti | 8GB | Up to 1x | Entry-level inference & experimentation | $0.097 / hr | Available Now | Launch |
| NVIDIA RTX 5070 | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.104 / hr | Available Now | Launch |
| Tesla P40 | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.108 / hr | Available Now | Launch |
| NVIDIA RTX 3080 Ti | 12GB | Up to 1x | Cost-efficient inference & prototyping | $0.110 / hr | Available Now | Launch |
| NVIDIA RTX 5060 Ti | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.122 / hr | Available Now | Launch |
| Titan RTX | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.136 / hr | Available Now | Launch |
| NVIDIA RTX 3090 | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.149 / hr | Limited | Launch |
| NVIDIA RTX A2000 | 6GB | Up to 1x | Entry-level inference & experimentation | $0.156 / hr | Available Now | Launch |
| NVIDIA RTX 5070 Ti | 16GB | Up to 1x | Cost-efficient inference & prototyping | $0.202 / hr | Available Now | Launch |
| Tesla V100 | 32GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.226 / hr | Available Now | Launch |
| NVIDIA A10 | 22GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.243 / hr | Available Now | Launch |
| NVIDIA RTX PRO 4000 | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.249 / hr | Limited | Launch |
| NVIDIA RTX PRO 4500 | 32GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.276 / hr | Available Now | Launch |
| NVIDIA RTX 3090 Ti | 24GB | Up to 1x | Image/video generation, mid-tier AI workloads | $0.338 / hr | Available Now | Launch |
| NVIDIA RTX PRO 4500 SE | 32GB | Up to 8x | Image/video generation, mid-tier AI workloads | $0.720 / hr | Available Now | Launch |
| NVIDIA RTX PRO 5000 | 48GB | Up to 1x | Fine-tuning, mid-size training, inference | $0.739 / hr | Available Now | Launch |
SSH into a dedicated GPU instance, install what you need, and run it exactly like your own server.
Dedicated for the full duration of your session — no sharing, no noisy neighbors.
PyTorch, TensorFlow, vLLM, ComfyUI — or bring your own Docker image. See all templates →
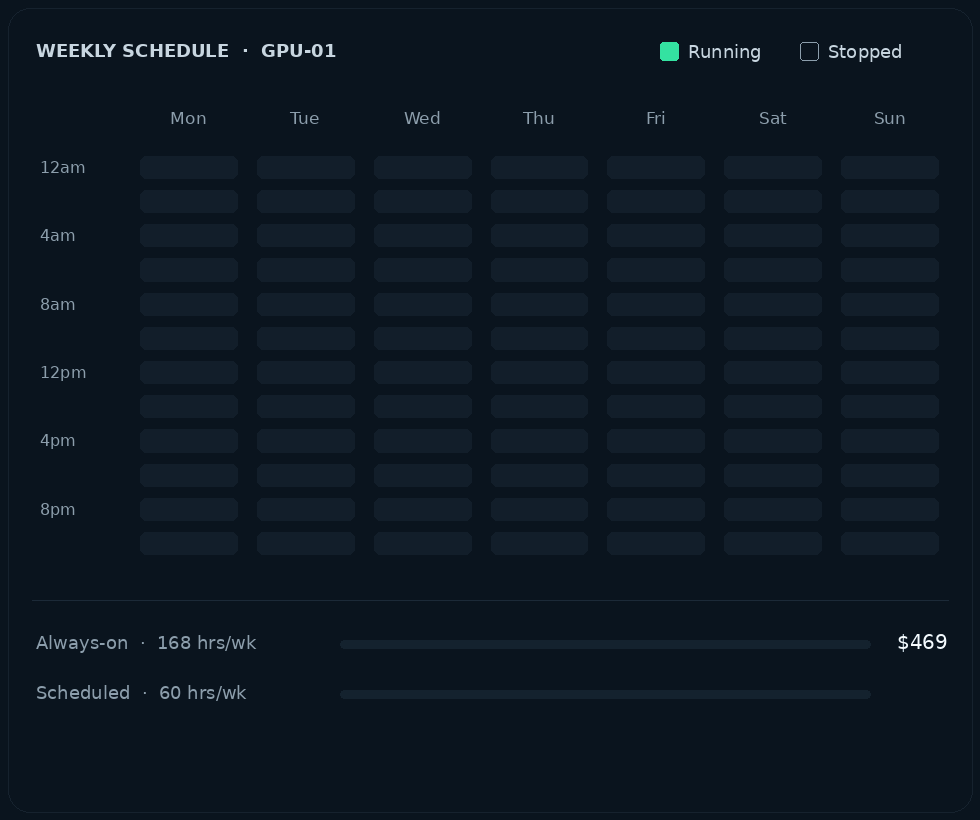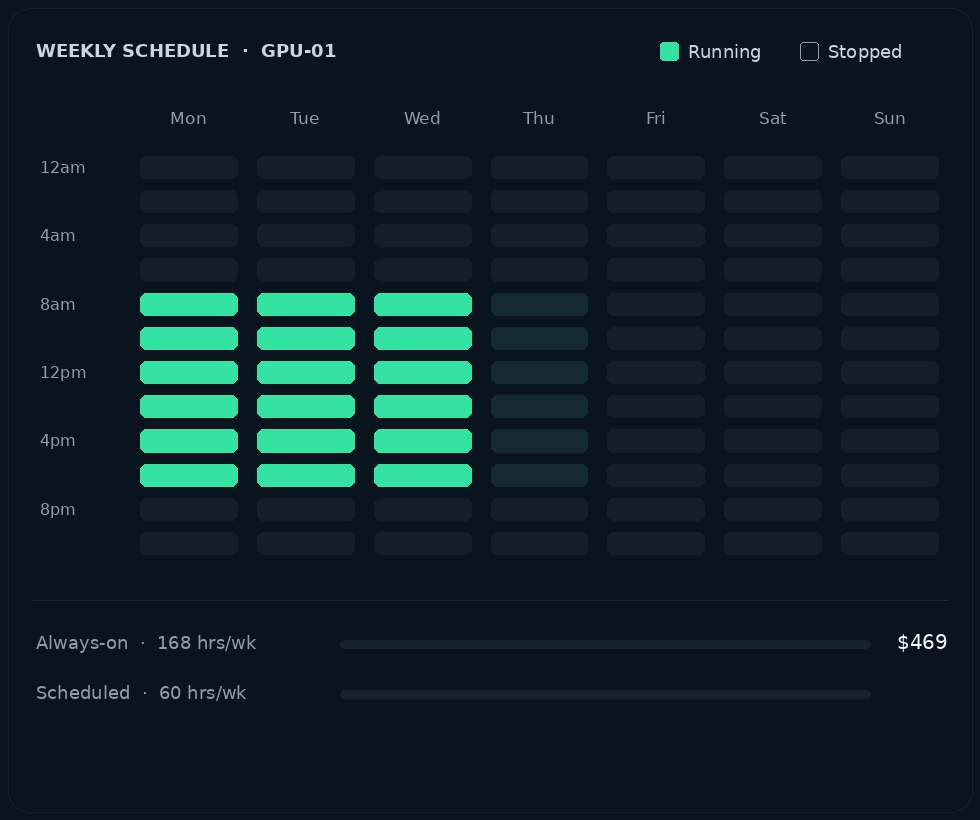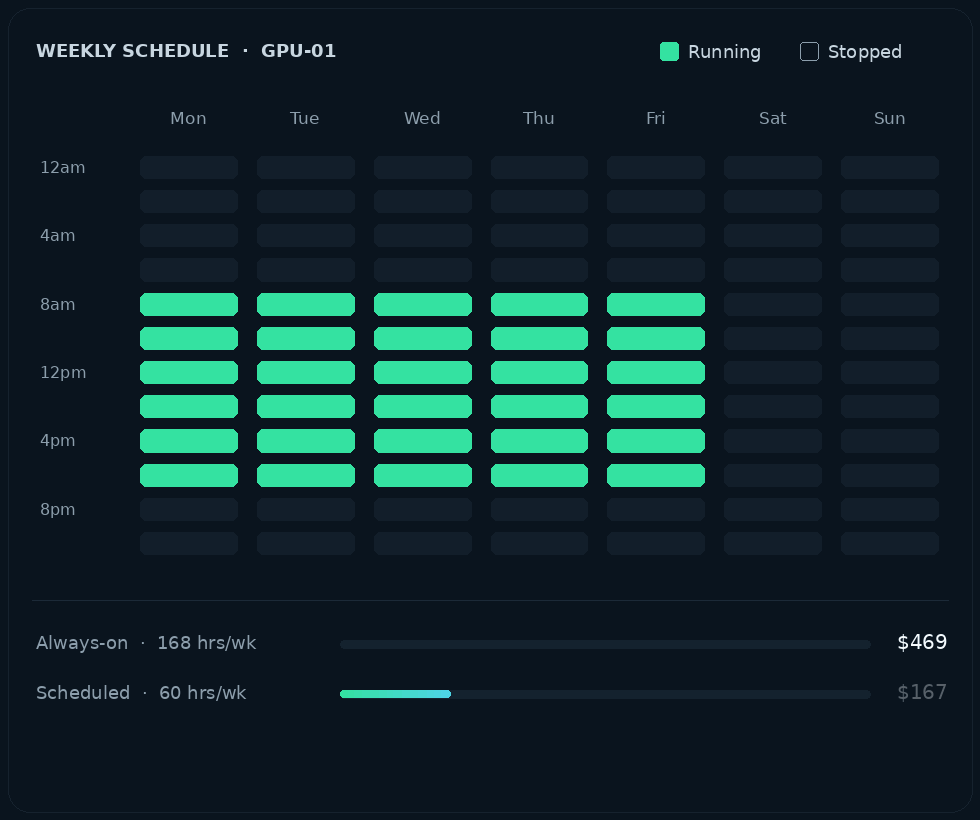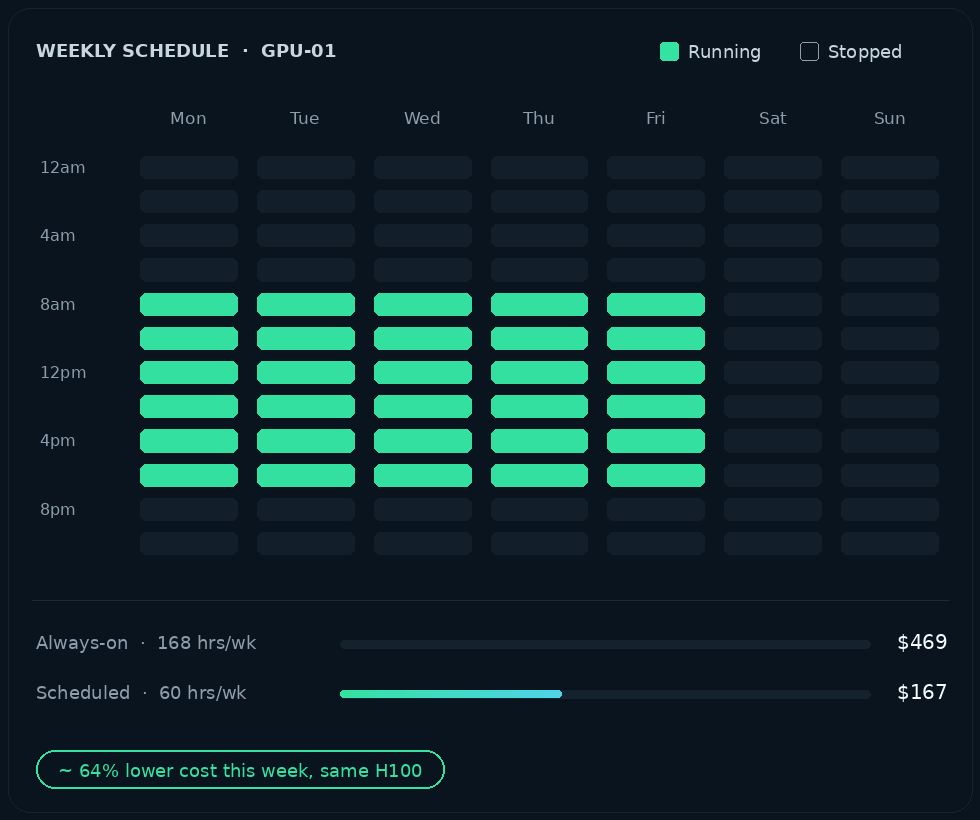
GPU Cloud is billed per hour, and you control exactly what you pay for by controlling when your instance runs.
Pause an instance the moment you're done, and pick up exactly where you left off.
Set recurring on/off windows — business hours only, or overnight training runs — so you never pay for idle time.
This is what makes GPU cloud different from renting from one provider. If the specific GPU your instance needs isn’t available when you try to start it, here’s what happens automatically.

InstantGPU automatically searches for an equivalent GPU — same model class, same region — across our connected providers.

If a match is found, your instance is migrated automatically. You don't re-provision anything.

If nothing equivalent is available, you're notified with the closest options. You choose, and we handle the migration.
Work that needs dedicated GPU memory and bandwidth, not shared or bursty capacity.
Burst capacity when you need it, without signing a long-term cloud contract.
Training jobs and interactive notebooks that don't fit a Serverless cold-start model.
Move fluidly between a dedicated GPU Cloud instance, a Serverless function, and a Public Endpoint — all under one account.

Instead of separate contracts with every GPU vendor.

Continuously sourcing capacity and pricing across multiple GPU clouds.

If capacity disappears, migration happens automatically.
GPU Cloud gives you a dedicated, always-on instance you control directly — SSH access, your own environment, persistent storage. Serverless is for event-driven functions that scale to zero when idle, better suited to inference workloads with unpredictable traffic.
Your persistent volume and workspace data are preserved during automatic migration. The system moves your instance to an equivalent GPU without requiring you to re-provision or manually transfer data.
Yes — deploy any custom Docker image on GPU Cloud alongside the pre-built templates for PyTorch, TensorFlow, vLLM, and ComfyUI.
No — GPU Cloud is billed per hour with no long-term contract required. Stop, start, or schedule your instance whenever you need to.
100+ GPU types across 4 GPU families, from entry-level cards to frontier hardware like the H200 and B200, with live per-hour pricing starting at $0.03/hr.
No sales call required create an account and add a payment method to get started.