Model description
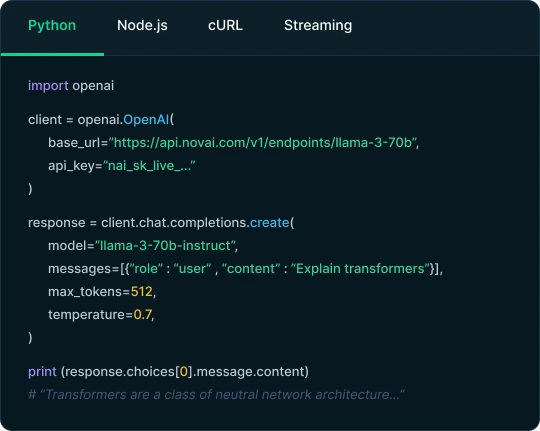
Execute job request via HTTP POST
Check the status of a job execution
Run asynchronous job and poll for result in Python

Conversational products with memory, tool use, and multi-turn context handled for you.

Generate drafts, rewrite copy, or condense long documents and threads into key points.

Structured extraction, classification, and multi-step reasoning pipelines with typed output.