LLM Inference Hosting
Run LLM Inference Without Building Your Own GPU Infrastructure
Running a large language model in production is very different from experimenting with a model on a local machine.
As soon as an application starts receiving real users, teams have to think about GPU memory, model loading, concurrency, latency, scaling, monitoring and infrastructure cost. Moreover, A model that works perfectly in a development environment can become expensive or unreliable when inference traffic increases.
LLM inference hosting gives developers a way to run language models on GPU infrastructure without building and maintaining the entire serving stack themselves.
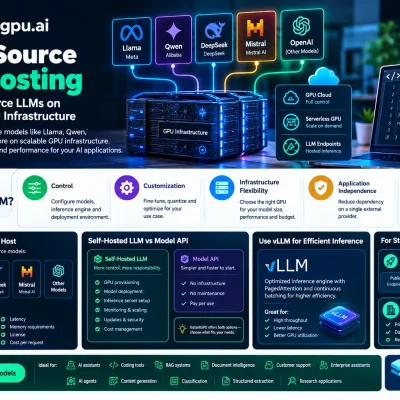
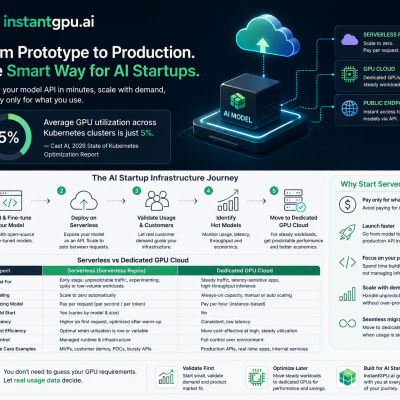
InstantGPU provides three ways to run production AI workloads: dedicated GPU Cloud for full infrastructure control, Serverless for variable workloads, and Public Endpoints for calling supported models through an API.
What Is LLM Inference Hosting?
LLM inference is the process of running a trained language model to generate an output from an input prompt.
Unlike model training, inference is typically a recurring production workload. A chatbot may generate thousands of responses every day. A coding assistant may process requests continuously. A document-processing application may send large batches of prompts to an LLM.
LLM inference hosting provides the GPU compute and model-serving infrastructure required to perform this work.
Depending on the workload, an application may require:
- High-memory GPUs
- Fast model loading
- Efficient GPU utilization
- Continuous or dynamic batching
- Low-latency inference
- Autoscaling
- API access
- Persistent model storage
- Monitoring and request metrics
Further, The right architecture depends on traffic patterns and the model being deployed.
Why Use GPU Infrastructure for LLM Inference?
Modern language models can require substantial GPU memory and compute.
Smaller models can often run on a single GPU, while larger models may require high-memory GPUs or multiple GPUs. Quantization can reduce memory requirements, while optimized inference engines can improve throughput and latency.
InstantGPU gives teams access to a wide range of GPU configurations so they can select infrastructure appropriate to their model.
For long-running or predictable workloads, GPU Cloud provides dedicated infrastructure with SSH access and full environment control.
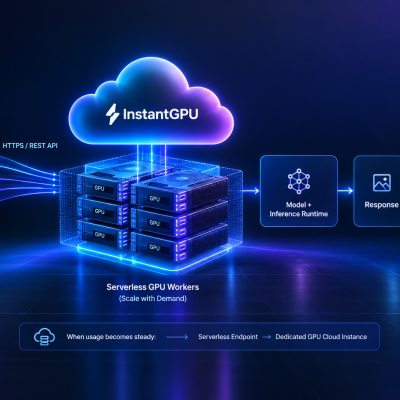
Also, For workloads with unpredictable demand, Serverless GPU can automatically scale workers based on traffic and scale to zero when idle.
For teams that simply want to consume a model through an API, Public Endpoints remove the need to manage GPU infrastructure.
LLM Inference Hosting Options
Dedicated GPU Cloud
Dedicated GPU Cloud is suitable when you need:
- Persistent model loading
- Full SSH access
- Custom CUDA environments
- Long-running inference
- Fine-tuned models
- Custom inference servers
- Predictable workloads
You can select a GPU, configure the environment and run your preferred model-serving stack.
Serverless LLM Inference
Serverless is designed for applications where traffic changes over time.
Instead of paying for an always-running GPU, your inference workload can run when requests arrive and scale down when demand disappears.
This can be useful for:
- AI SaaS applications
- Prototype applications
- Internal AI tools
- API workloads
- Event-driven pipelines
- Applications with unpredictable traffic
LLM API Endpoints
If infrastructure management is not part of your product’s value proposition, an API-based approach may be simpler.
InstantGPU provides hosted language models through an API-compatible interface, allowing developers to integrate language models without managing the underlying GPU environment.
What Can You Build With LLM Inference?
LLM inference infrastructure can power:
AI Chatbots
Deploy conversational AI for customer support, internal knowledge assistants and consumer applications.
AI Coding Assistants
Run models designed for code generation, code explanation, debugging and software development workflows.
Document Processing
Use LLMs for classification, extraction, summarization and structured data generation.
RAG Applications
Combine vector retrieval with LLM inference to create applications that answer questions using private or frequently changing information.
AI Agents
Agents use language models repeatedly as they reason, call tools and execute tasks. Reliable inference infrastructure becomes increasingly important as agent workloads scale.
LLM Inference With InstantGPU
InstantGPU lets teams choose the infrastructure model that matches their workload instead of forcing every application into the same architecture.
GPU Cloud provides control.
Serverless provides elasticity.
Public Endpoints provide simplicity.
This allows an AI application to move from experimentation to production without completely changing its infrastructure strategy.
Why InstantGPU?
InstantGPU is designed as a multi-cloud GPU platform rather than a single-provider GPU marketplace.
The platform currently sources GPU capacity across multiple providers and supports a broad range of GPU configurations.
This matters because GPU availability can change quickly. Instead of depending on one provider’s capacity, InstantGPU can search across its connected infrastructure providers and support workload migration when appropriate.
For developers, this means less time spent hunting for available GPUs and more time building the actual AI application.
When Should You Use LLM Inference Hosting?
LLM inference hosting is a strong fit when you need to:
- Deploy an open-source LLM
- Run a private language model
- Build an AI SaaS product
- Serve a fine-tuned model
- Build a RAG application
- Power an AI agent
- Reduce dependence on a single model API
- Control your inference infrastructure
- Scale GPU inference with application demand
Start Running LLM Inference
Whether you need a dedicated GPU, a serverless inference function or a production-ready model API, InstantGPU provides a path from model experimentation to production deployment.
Explore LLM inference, compare available infrastructure through GPU Cloud, or deploy variable workloads with Serverless GPU.

FAQ’S
Frequently Asked Questions
What is LLM inference hosting?
LLM inference hosting provides the GPU infrastructure and model-serving environment required to run a large language model and generate responses for applications.
What GPU do I need for LLM inference?
The GPU requirement depends on model size, precision, context length, concurrency and latency requirements. Smaller quantized models can run on lower-memory GPUs, while large models may require high-memory or multi-GPU configurations.
Can I host an open-source LLM?
Yes. With GPU Cloud or Serverless infrastructure, developers can deploy compatible open-source models and their own model weights.
Is serverless GPU good for LLM inference?
Serverless GPU can be useful for variable or event-driven inference workloads because capacity can scale based on demand instead of requiring a continuously running GPU.
Can I use an LLM through an API?
Yes. InstantGPU provides hosted language-model endpoints that can be accessed programmatically through an API.
What is the difference between LLM hosting and LLM inference?
LLM hosting refers broadly to making a model available on infrastructure. LLM inference specifically refers to running that model to generate predictions or responses for requests.
Internal-link plan for this page
- Existing AI Startup Model Hosting → startup use case
- GPU Cloud → dedicated hosting
- Serverless → elastic inference
- LLM Inference → conversion/product page
- Pricing → commercial intent
- Endpoints → API route
Type your paragraph here