ENGINEERING How we hit 340ms cold starts on H100 GPUs A breakdown of every millisecond — from container scheduling to CUDA context init and VRAM prefetching. Reading progress 0%
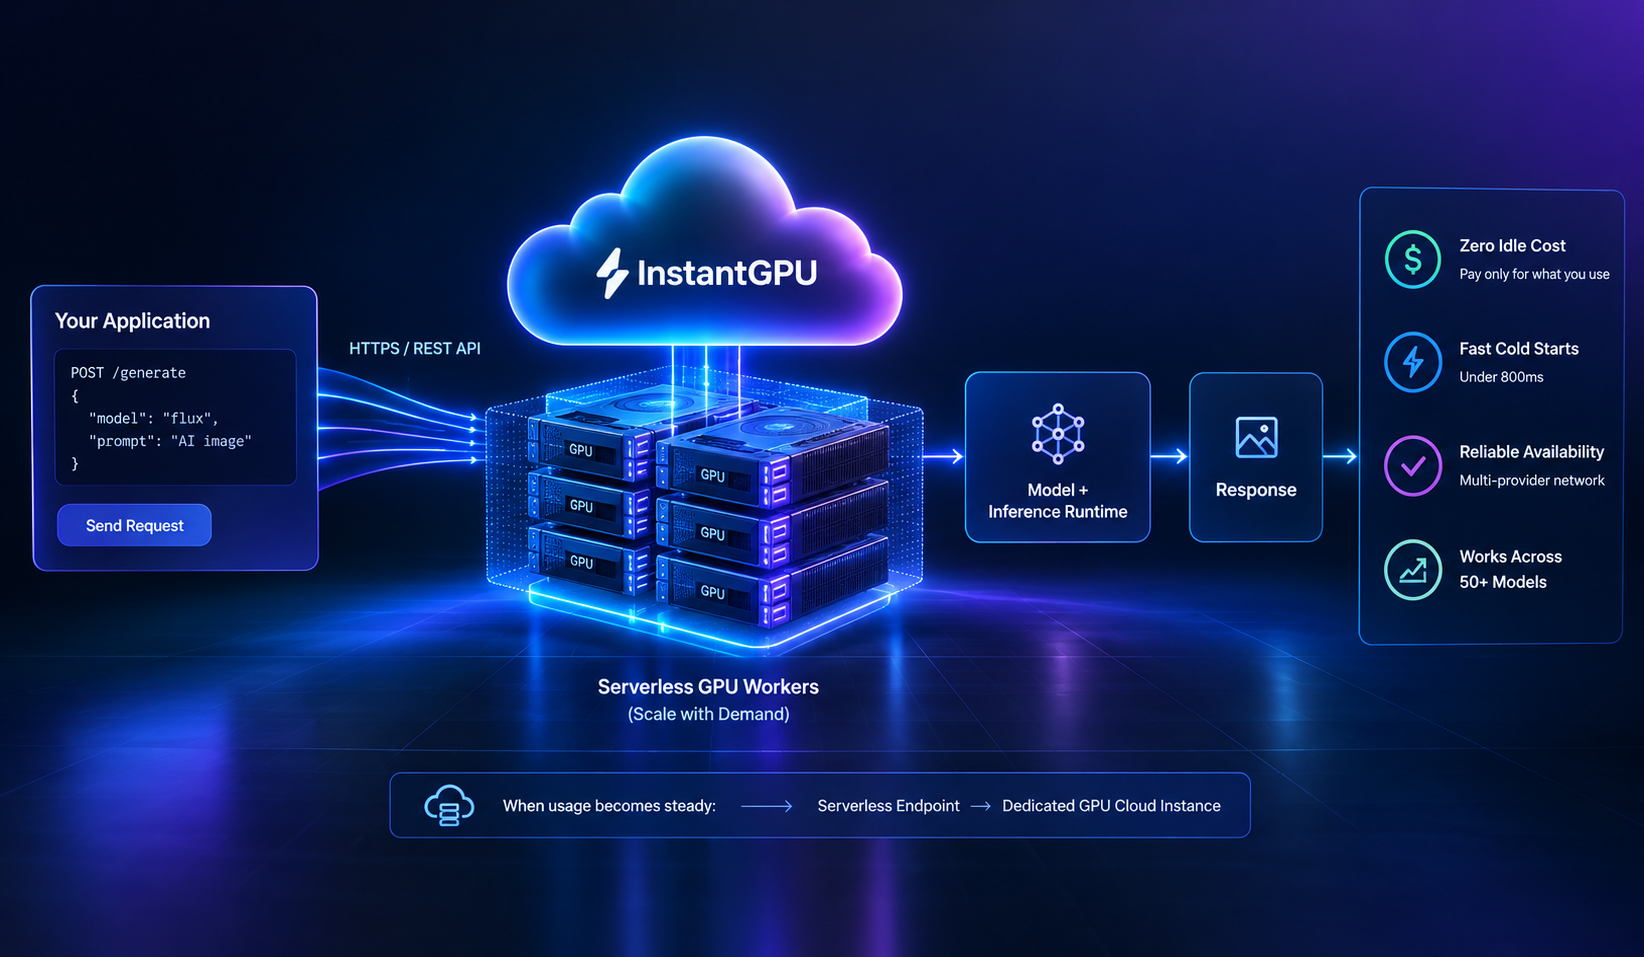
Truly Serverless GPU Discover what a truly serverless GPU platform means, from zero idle costs and fast cold starts to reliable GPU availability across AI workloads. Oct 2026
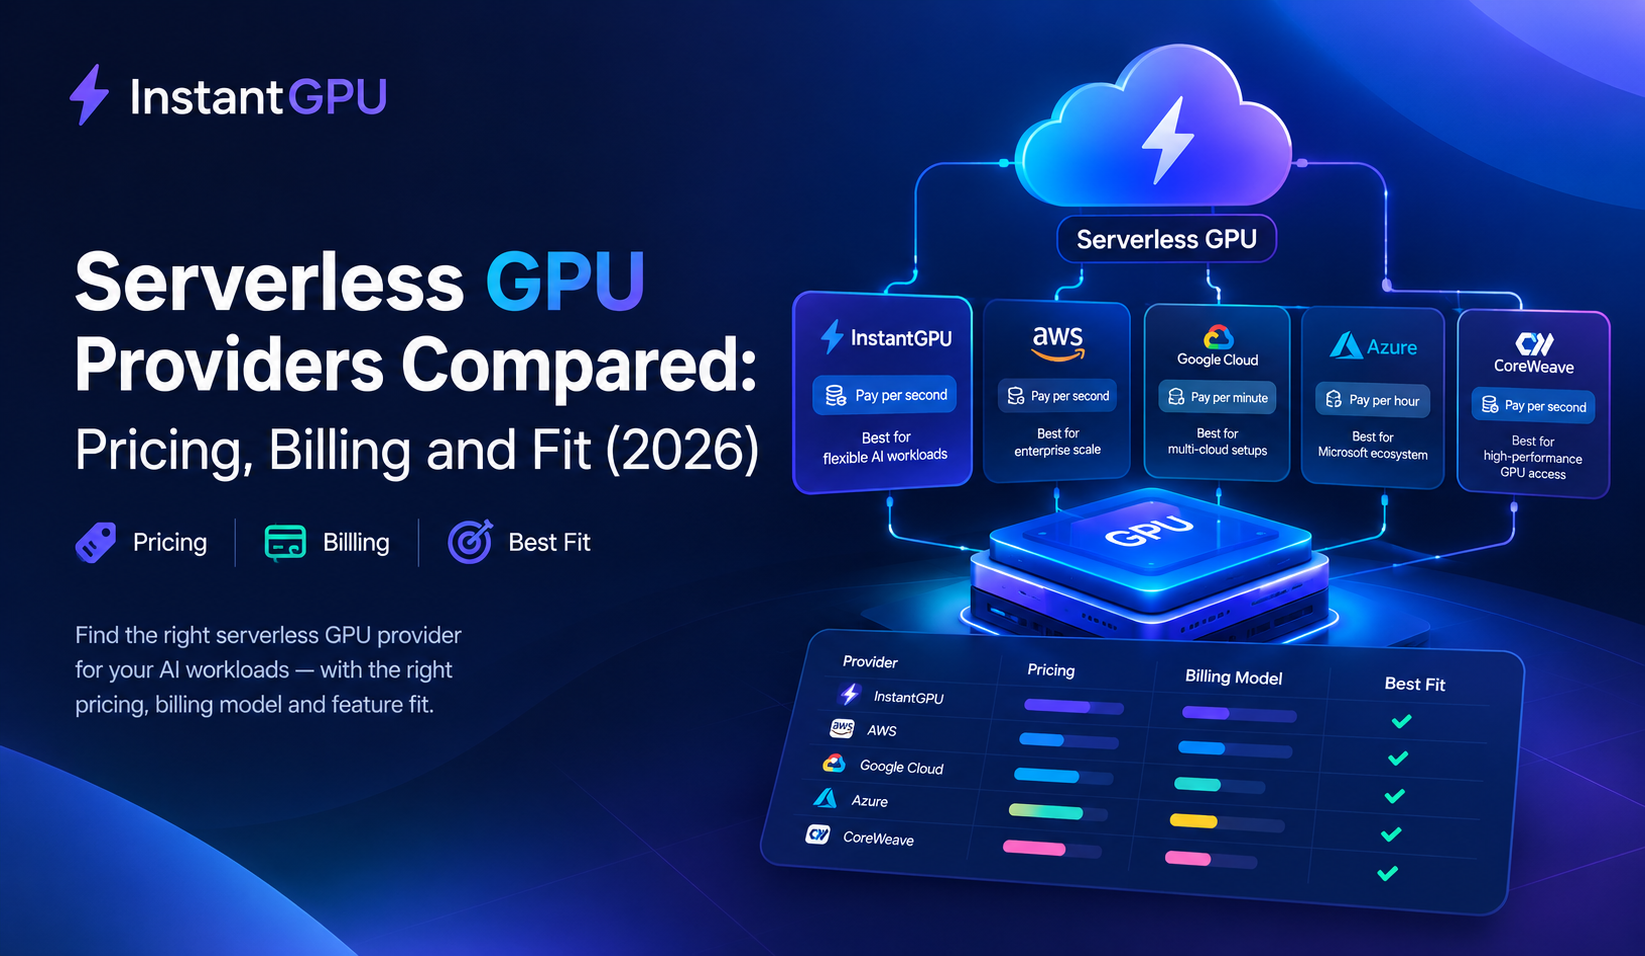
Serverless GPU Providers Compared Compare Top serverless GPU providers by billing unit, listed H100 price and idle cost, as of September 2026. Includes a break-even guide and FAQ Sep 2026
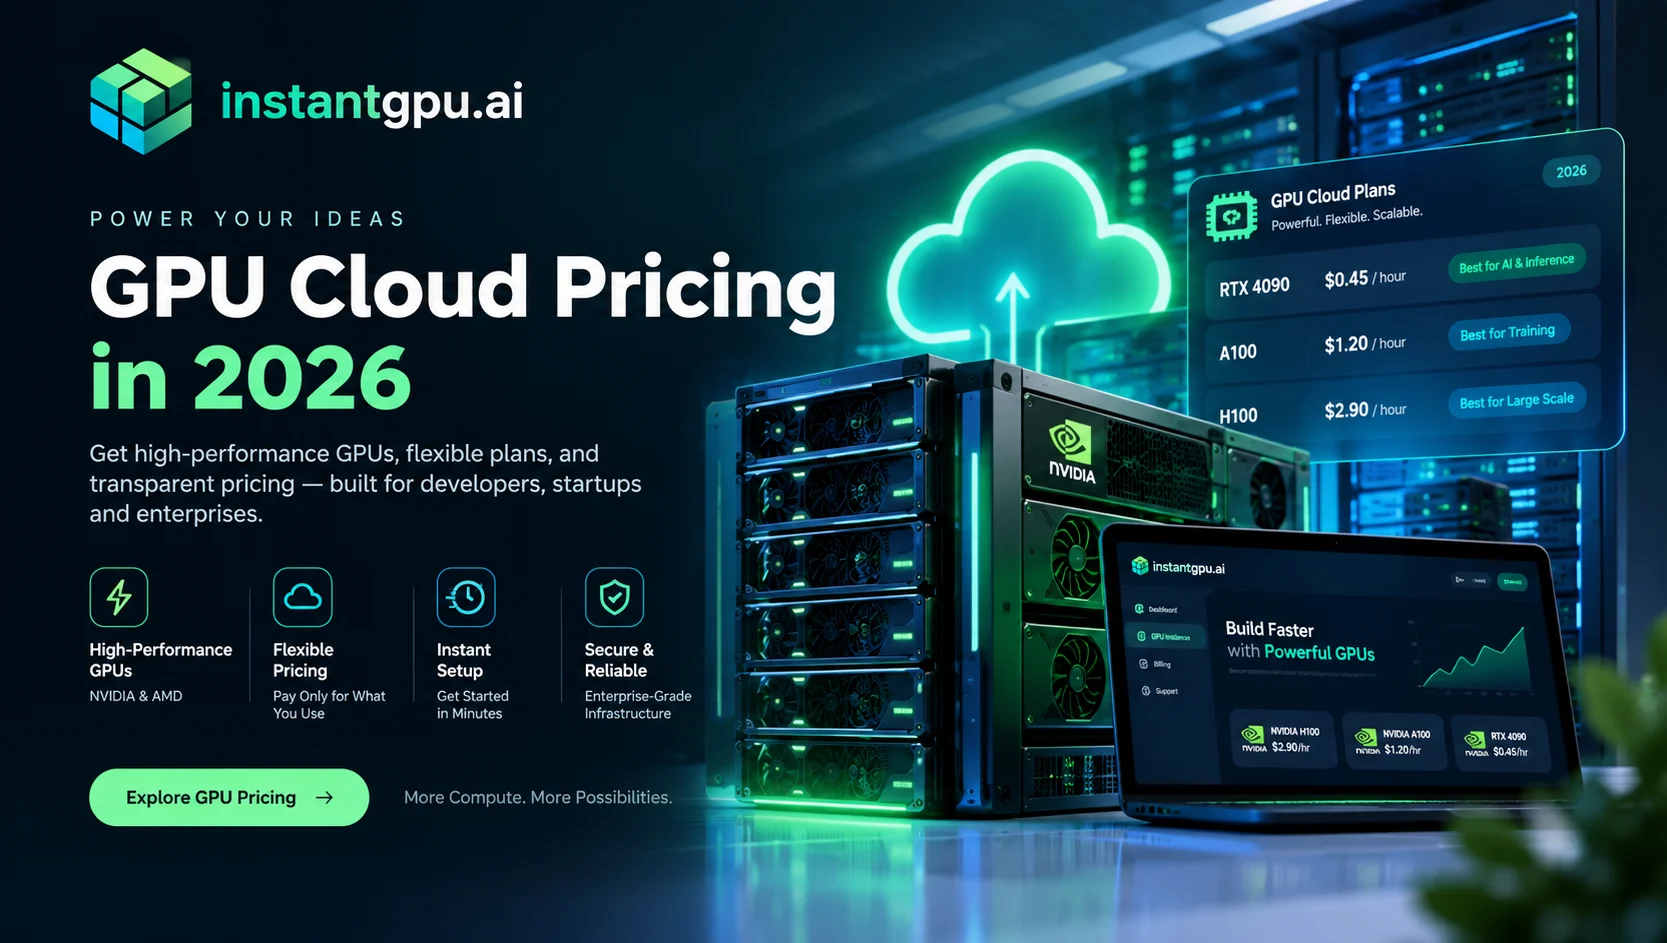
GPU Cloud Pricing Compare live GPU cloud pricing across 100+ GPUs, from H100 to RTX 4090, and discover real market rates beyond hyperscale's. Sep 2026
GPU Availability GPU availability, not cold-start speed, is the real bottleneck in AI infra. See how InstantGPU.ai solves GPU availability through multi-cloud sourcing and automatic migration across 100+ GPU types. Sep 2026
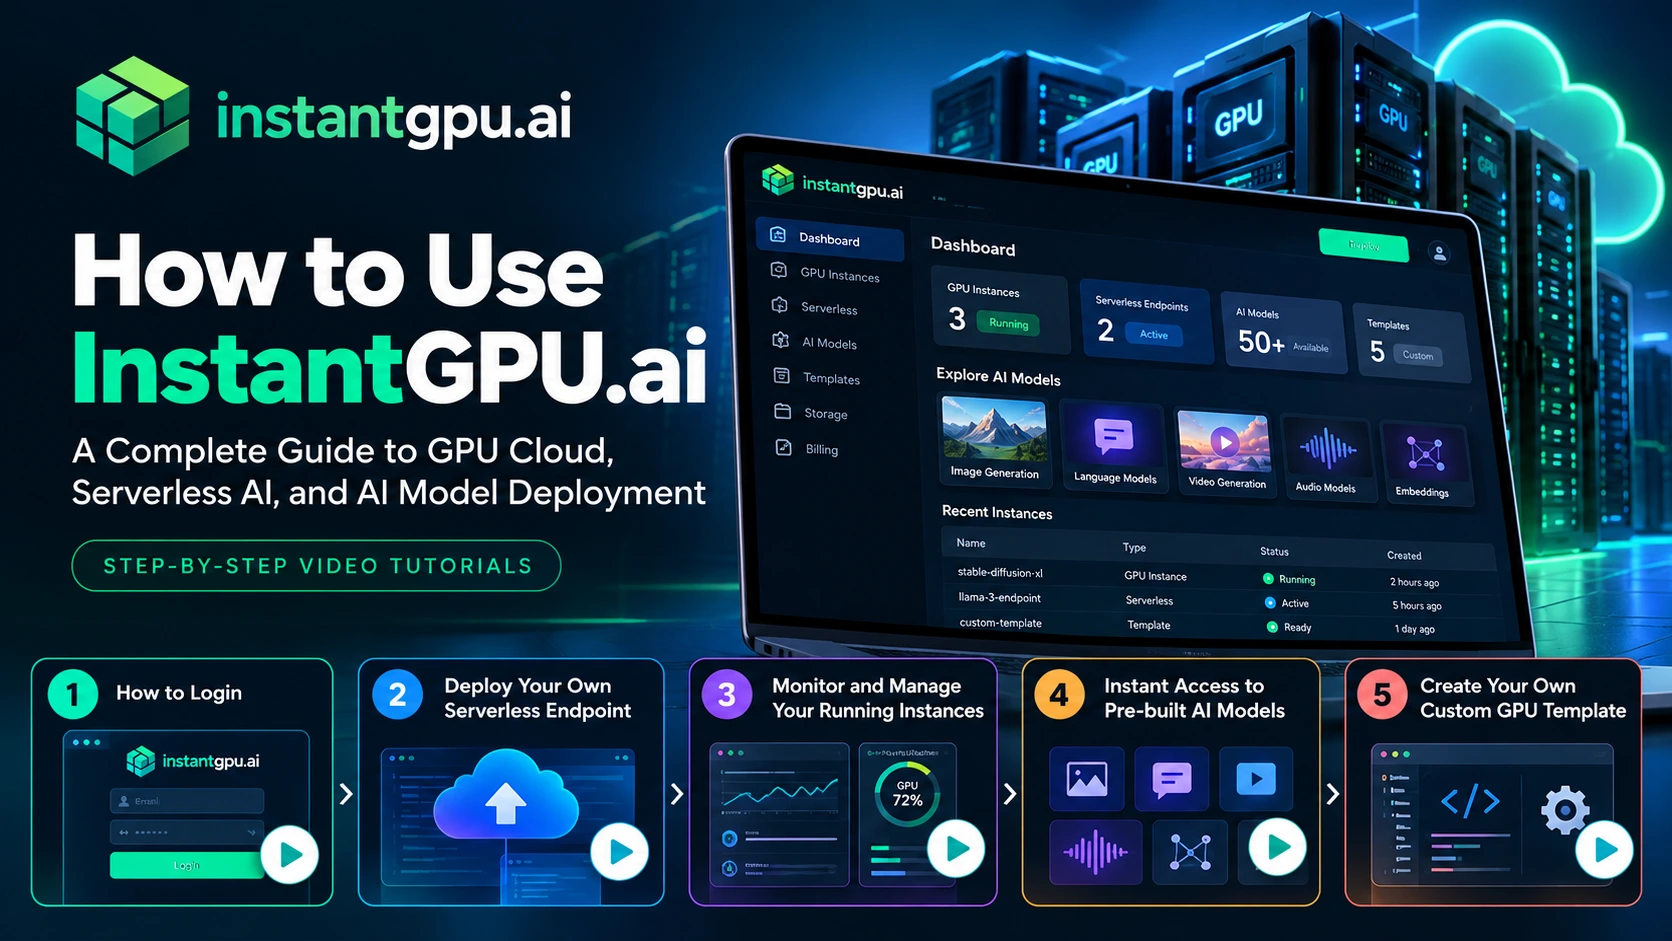
How to Use InstantGPU.ai: A Complete Guide to GPU Cloud, Serverless AI, and AI Model Deployment AI art tools are reshaping how artists and studios create — from text-to-image generation to real-time editing. See how it works and what powers it at scale. Dec 2025