PUBLIC ENDPOINTS

Production-ready AI APIs, zero infrastructure

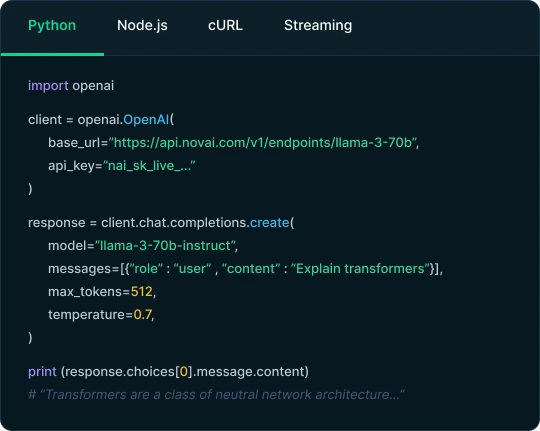
Call best-in-class open and hosted models for image, video, audio, language, and embeddings — one API, pay-per-use, no servers to manage. Try every endpoint in the Playground before you write code.

5 modalities

Pay-per-use pricing

1 consistent API

ONE API
POST /v1/endpoints/{mode}
Image
Video
Audio
Language
Embed

BROWSE BY MODALITY

Five Modalities, one API pattern

Each category links to its own set of models, benchmarks, and pricing.

Image Generation

Text-to-image and image-to-image models.

Video Generation

Text-to-video and image-to-video models.

Audio AI

Text-to-speech, speech-to-text, and voice models.

Language models

Open-source and hosted LLMs for chat & reasoning.

Embeddings

Vector embedding models for search and RAG.
Why Public Endpoints

Why Public Endpoints

Zero infrastructure
No provisioning, scaling, or maintaining — models spin up and scale automatically behind one API.
Pay-per-use pricing
No idle cost when you're not calling the endpoint.
Test before you integrate
Try any model in the Playground, so you're not guessing at output quality or latency.
One consistent API pattern
Switching models doesn't mean rewriting your integration code.

HOW IT WORKS

How It Works

Find a modal

Browse the category that fits your use case — image, video, audio, language, or embeddings.

Test it live

Run it in the Playground with your own input — no API key required to try it out.

Call your endpoint

Grab your API key and call the same endpoint from your code.

DASHBOARD

Your Endpoints

Live status, metrics, and controls for all deployed serverless endpoints.

NAME - MODEL
STATUS
HARDWARE
REQUESTS / MIN
AVG LATENCY
llama-3-70b-instruct
prod-inference-v3
Active
H100 SXM5
1,240
184ms
mixtral-8x22b
staging-moe-test
Cold
A100 80G
0
—
whisper-large-v3
transcription-api
Active
A10G
327
420ms
sdxl-turbo
image--gen-exp
Paused
A100 40G
0
—
Model Name
sub-id
Active
H100
0
-

PERFORMANCE

Cold Start Breakdown

We’ve obsessively optimized every millisecond of container initialization.

Total cold start time • p50

340ms
H100 • Llama 3 70B • 8-bit quantized
Oms 60ms 180ms 280ms 340ms
Container start
Model cache fetch
vRAM loading
First token
~340ms
p50 cold start
~680ms
p99 cold start
~18ms
p50 warm latency
10GB/s
model cache speed

One API Five modalities

Try any model in the Playground — no API key required to get started.