ENDPOINTS · LANGUAGE

LLM Inference for Fast, Scalable AI Applications

LLM Inference Chat, completion, reasoning, and structured output — call leading open-source and hosted language models without managing GPU infrastructure. Compare models side by side in the Playground.

9+ models live

128k max content

OpenAI-compatible

WHAT YOU CAN BUILD

What you can build

From conversational products to backend reasoning pipelines — one API surface for every text workload.

Chatbots and Assistants

Conversational products with memory, tool use, and multi-turn context handled for you.

Content and Summarization

Generate drafts, rewrite copy, or condense long documents and threads into key points.

Extraction and Reasoning

Structured extraction, classification, and multi-step reasoning pipelines with typed output.
DROP IN COMPATIBLE

Works with your existing OpenAI SDK

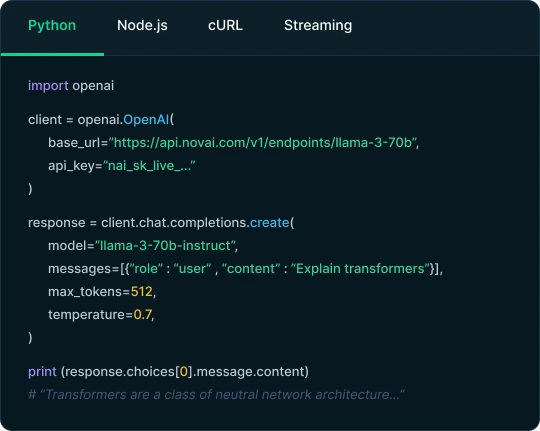
Our API follows the OpenAI request and response format. If your code already speaks to openai.chat.completions.create, it works here too — swap two values and keep everything else.
Same request shape
Messages, roles, temperature, streaming — all unchanged.
Two lines to switch
Point base_url at instantgpu.ai and use your instantgpu key.
Any official SDK
Python, Node, and community OpenAI-compatible clients all work as-is.

Bring your own prompts

Start comparing models in the Playground — swap the base URL when
you’re ready to ship.