SERVERLESS

Deploy. Ship, Sleep

Push AI code from a template or your own repo to run serverless GPU workloads. We handle containers, scaling, and cold starts — you pay only for the seconds your GPU is actually running.

per hour billing

0 → N auto-scaling

100s of templates

RUNNING
GPU 1x H100 80GB
REGION us-east
STORAGE 200GB persistent
TEMPLATE PyTorch 2.4
GPU Utilization 60%

HOW IT WORKS

Serverless GPU from template to endpoint in minutes

Choose a template

100s available for common frameworks and models — or bring your own container.

Deploy

We provision GPU workers on demand across our connected providers.

Call your endpoint

An API is ready immediately — no infrastructure to manage.

Scale automatically

Workers scale to zero when idle and back up under load — never pay for unused capacity.

BUILT FOR VARIABLE WORKLOADS

Built for variable, event-driven workloads

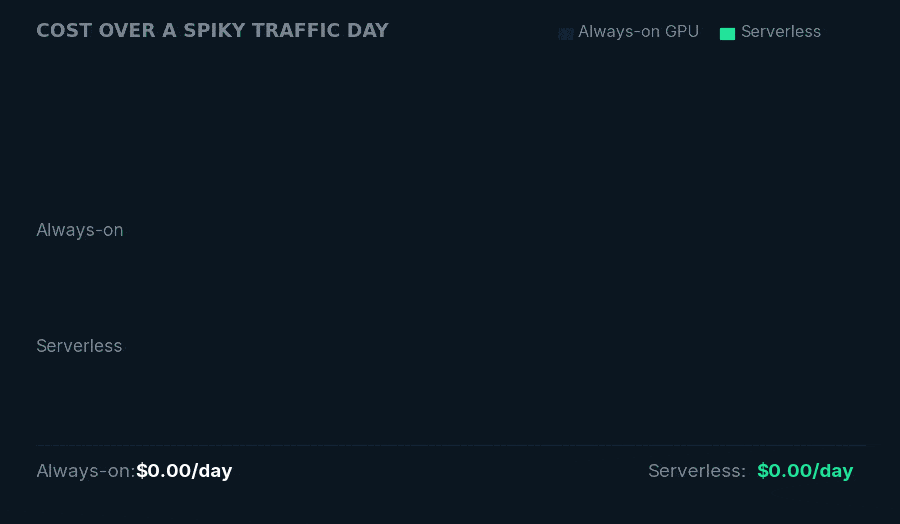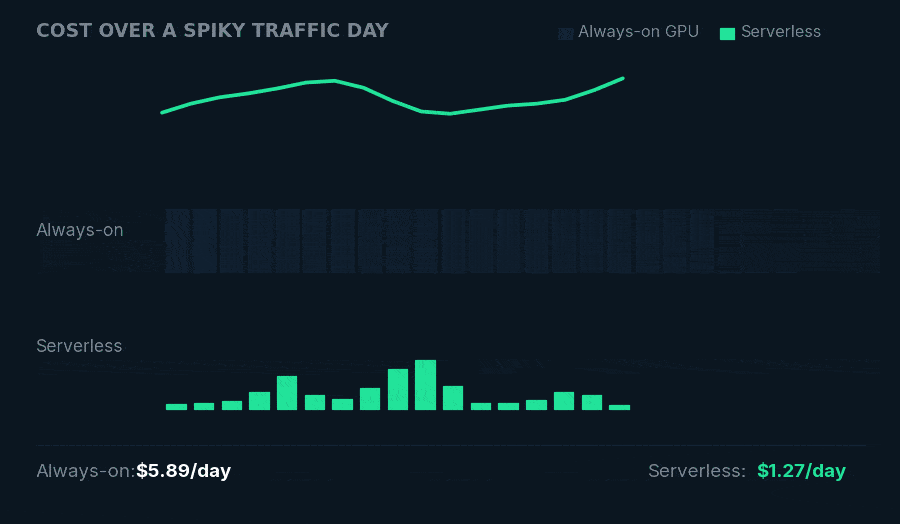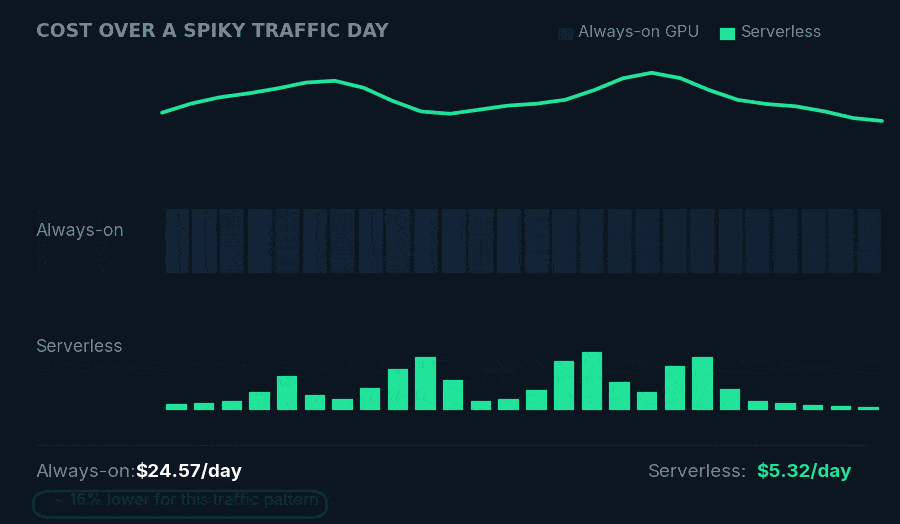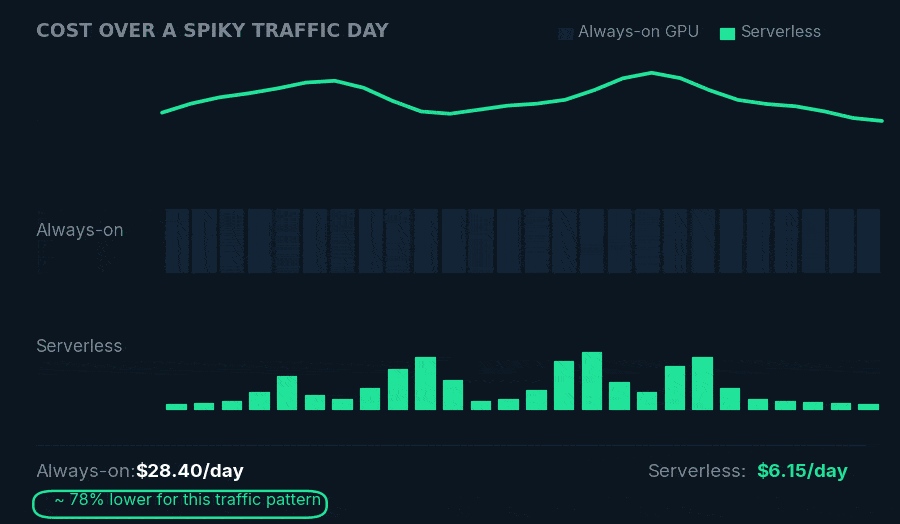
Per-second billing

Pay only while your function is executing.

Automatic scale-to-zero

No traffic, no cost — serverless GPU workers spin down when idle.

Burst without planning

Scale to many concurrent workers under load, with no capacity planning needed.

Deploy from 100s of templates or your own Docker image — same template library as GPU Cloud.  See all templates →

WHO IT’S FOR

Built for Shipping, not managing servers

Product teams shipping inference APIs

Image generation, chat, transcription — features with unpredictable traffic on serverless GPU inference.

Developers who don't want ops

Image generation, chat, transcription — features with unpredictable traffic.

Fast prototyping

Start from a template before committing to a dedicated GPU Cloud instance.

GPU CLOUD

Raw GPU power, on demand

From single A100s to multi-node H100 clusters — spin up bare-metal on-demand GPU capacity in under a minute with no scheduling queues.

GPU CLOUD

Git push
We handle the rest

Connect your repository once and get fully automated build, test, and deployment pipelines. Zero-downtime blue/green deploys on every commit.

Connect you repo

One-click GitHub / GitLab integration. We listen to push events on any branch you configure.

Automatic container build

We detect Python, pin CUDA, cache your requirements.txt, and produce a reproducible image in seconds.

Canary → production

New builds get 10% of traffic first. If health checks pass, traffic shifts 100% with no downtime.

Instant rollback

Every deploy is versioned. Roll back to any previous build in one click or one CLI command.

neuralcore - deployment graph
main feature/new-model
v2.1.0
fix: OOM branch
feat: llama-4
merge
LIVE ✓
Build: 38s
14:22:01 ✔ Push detected - main - a3f9b2c
14:22:03 → Building container (CUDA 12.4 - Python 3.11)
14:22:18 ✔ Deps cached - Layer reused (2.1 GB)
14:22:29 ✔ Model weights loaded - 7.2 GB from cache

SUPPORTED RUNTIMES

Bring your Stack.
We’ll run it.

Any Python framework, any model hub, any GPU. We auto-detect
and configure the right CUDA base image.

PyTorch

2.3 - CUDA 12.4

HuggingFace

Transformers 4.x

vLLM

0.5 - PagedAttn

TensorRT

10.x - FP8

Diffusers

SDXL - Flux

llama.cpp

GGUF - GGML

JAX

0.4 - XLA

AudioCraft

MusicGen - MACs

OpenMM

Protein - Mol

Custom

Any CUDA image
FAQ’S

Serverless GPU FAQ's

What is serverless GPU inference?

Serverless GPU inference lets you deploy AI functions that automatically scale to zero when idle and scale up under load, billing you only for the seconds your GPU is actively running — no idle capacity, no manual provisioning.

[Insert real measured cold-start benchmark here once available — mean/median seconds from a scaled-to-zero function to first response, by model size.]

Serverless deploys event-driven functions that scale to zero and bill per second — best for variable, unpredictable traffic. GPU Cloud gives you a dedicated, always-on instance with full SSH access, billed per hour — best for long-running training and fine-tuning.

Yes — deploy any custom container, or choose from 100s of pre-built templates for PyTorch, HuggingFace, vLLM, TensorRT, Diffusers, and more.

Every push triggers an automated build, a canary deploy to 10% of traffic, health checks, and a zero-downtime rollout to 100% traffic if checks pass — with instant rollback to any previous version if needed.

PyTorch, HuggingFace Transformers, vLLM, TensorRT, Diffusers, llama.cpp, JAX, AudioCraft, OpenMM, and any custom CUDA image.

Launch Your First Serverless GPU 

Deployment Today

GPU-powered workloads, run serverless AI functions, and access production-
ready model endpoints — all on one unified platform.